Compare the picture with the count table that made it
information visualization
word clouds
inaugural addresses
Learn how word clouds encode word counts, why the layout can mislead, and how to check the same words in a sorted table.
Twenty-two words can fill Iris’s slide about the inaugural addresses. The table behind the picture matters more than the shape of the picture itself.
The tempting part is also the risk. A large word can mean a high count, a long spelling, or a lucky position in the packing algorithm.
Word clouds draw words from a count table with larger type for larger counts. They are useful for a quick vocabulary preview. They are weak for exact comparisons, rank order, meaning, and change over time.
TipWhat you will learn
This lesson shows how to:
build one corpus-wide word-count table from inaugural paragraphs;
use a named stop-word lexicon and inspect what it removes;
draw a sorted bar chart and a word cloud from the same keyed counts;
keep word-cloud size, layout, and colour claims honest;
test a word-length trap with real words from the data; and
provide a two-part text alternative for the cloud.
Build one count table
The corpus helper returns one row per paragraph. This lesson asks one corpus-wide question: after a stated cleanup, which words occur most often across all inaugural paragraphs? That flattening weights long speeches more than short speeches, so the output is a vocabulary preview, not a claim about importance.
library(dplyr)library(tidyr)library(tibble)library(stringr)library(tidytext)library(ggplot2)library(ggwordcloud)library(purrr)library(knitr)source("R/inaugural-corpus.R")paragraphs <-inaugural_paragraphs()all_word_tokens <- paragraphs |>select(paragraph_id, speech_id, paragraph) |>unnest_tokens(word, paragraph)dropped_by_letters_filter <- all_word_tokens |>filter(!str_detect(word, "^[a-z]+$"))word_tokens <- all_word_tokens |>filter(str_detect(word, "^[a-z]+$"))onix_stop_words <- stop_words |>filter(lexicon =="onix") |>distinct(word)inaugural_word_counts <- word_tokens |>anti_join(onix_stop_words, by =join_by(word)) |>count(word, sort =TRUE, name ="count") |>mutate(word_key = word,letters =str_length(word) )cloud_words <- inaugural_word_counts |>slice_head(n =22) |>mutate(word_for_plot =reorder(word_key, count))count_table <- cloud_words |>transmute( word_key, count, letters )top_five_bars <- count_table |>slice_head(n =5)bar_alt_text <-sprintf(paste("Horizontal bar chart of 22 words.","The first five bars are %s (%s), %s (%s), %s (%s), %s (%s), and %s (%s).","Every bar comes from the same count table used for the cloud." ), top_five_bars$word_key[1], top_five_bars$count[1], top_five_bars$word_key[2], top_five_bars$count[2], top_five_bars$word_key[3], top_five_bars$count[3], top_five_bars$word_key[4], top_five_bars$count[4], top_five_bars$word_key[5], top_five_bars$count[5])cloud_alt_seed_7701 <-paste("Word cloud of the same 22 count-table words.","The largest words by count are government with 585 and people with 561;","the exact positions are not data.","The full count table above is the long text alternative.")stopword_note <-tibble(lexicon ="onix",removes_states ="states"%in% onix_stop_words$word,removes_united ="united"%in% onix_stop_words$word)kable( count_table,col.names =c("Word key", "Count", "Letters"),caption ="Top words after removing the onix stop-word lexicon from inaugural paragraphs",row.names =FALSE)
Top words after removing the onix stop-word lexicon from inaugural paragraphs
Word key
Count
Letters
government
585
10
people
561
6
so
384
2
country
306
7
world
305
5
nation
299
6
citizens
242
8
own
242
3
peace
240
5
power
240
5
public
224
6
time
214
4
constitution
207
12
united
198
6
nations
195
7
union
188
5
free
179
4
freedom
175
7
war
174
3
america
166
7
american
160
8
national
157
8
kable( stopword_note,col.names =c("Stop-word lexicon", "Removes `states`", "Removes `united`"),caption ="The named stop-word choice used for the count table",row.names =FALSE)
The named stop-word choice used for the count table
Stop-word lexicon
Removes states
Removes united
onix
TRUE
FALSE
The onix lexicon removes states but keeps united, so a phrase such as United States can leave united by itself. A different stop-word list would produce a different table.
unnest_tokens() lowercases the paragraphs and splits punctuation away from words. The ^[a-z]+$ filter keeps only tokens made entirely of letters, so it drops whole tokens such as america's; in this corpus it drops 367 tokens. After that filter and the onix stop-word list, so survives 384 times because so is not in the onix list.
Show the counts before the cloud
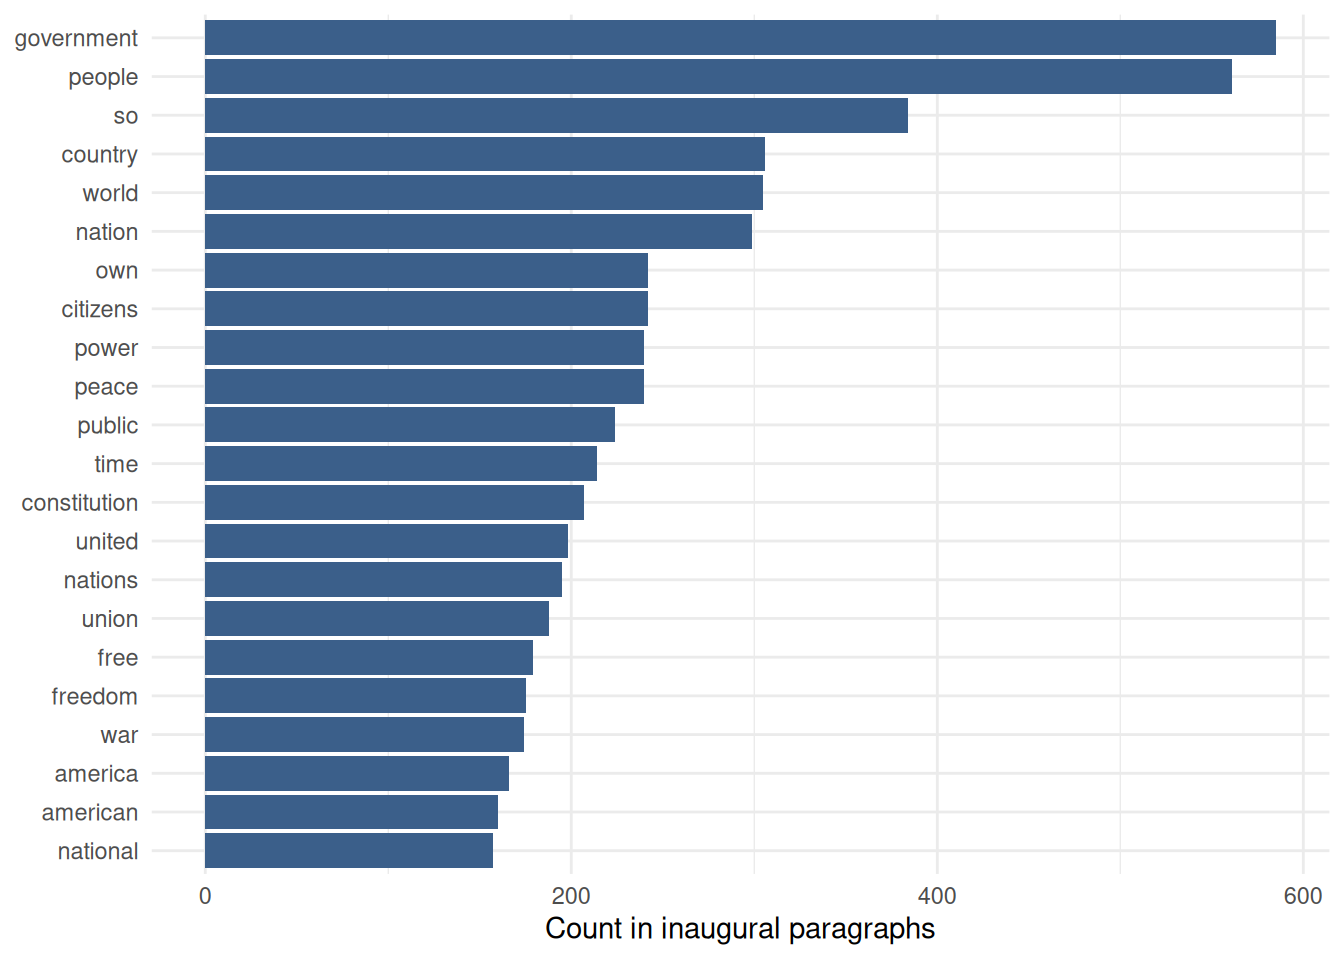
A sorted bar chart puts the same words on a common horizontal scale. Position along a common scale is easier to compare than text area, so the chart is the check Iris should read before the cloud. Cleveland and McGill placed area below position in their hypothesized ranking of graphical perception tasks; they did not run the word-cloud experiment on this page.
bar_plot <-ggplot(cloud_words, aes(x = count, y = word_for_plot)) +geom_col(fill ="#3B5F8A") +labs(x ="Count in inaugural paragraphs",y =NULL ) +theme_minimal()bar_plot
Figure 1: The 22 words used in the word cloud, sorted by count after onix stop-word removal.
The bar chart and the table use the same word_key and count values. No position in the later cloud is evidence of a relationship between words.
Draw the same counts as a cloud
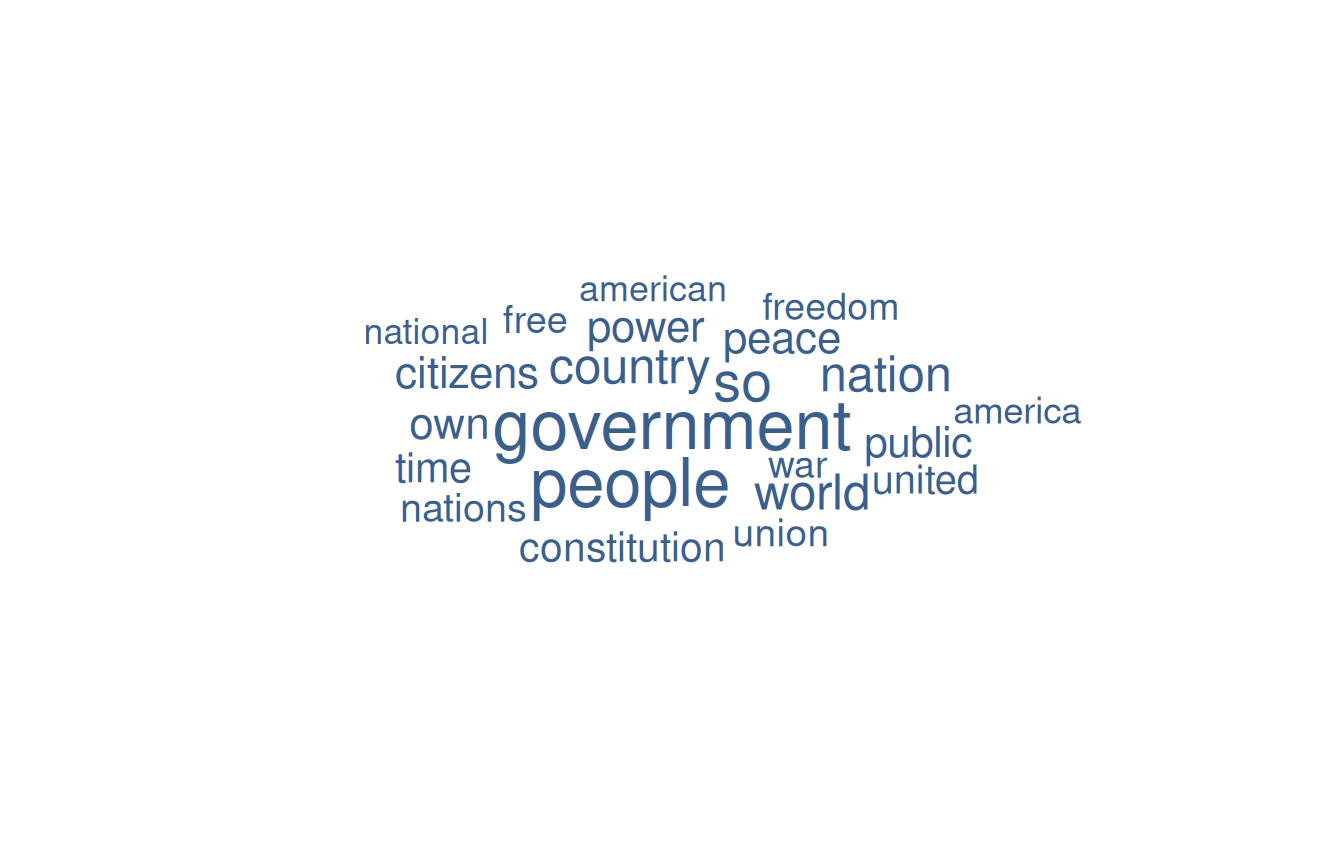
The cloud below uses geom_text_wordcloud() with one colour and no rotation. scale_size_area() maps the numeric count through an area scale for the size aesthetic: a count of zero would map to zero, and the largest count maps to the largest font size in this plot. Font size grows with the square root of the count, so each letter’s area follows the count, and a word’s whole footprint also grows with its number of letters. It does not divide by word length. A longer word can still cover more horizontal space than a shorter word with a similar or even larger count.
Figure 2: A word cloud drawn from the same 22 counts as the bar chart, using seed 7701.
The middle word is the first row drawn, not the topic of the speeches. Because the table is sorted by count, government is drawn first. If the table were alphabetical, a different word could start in the centre. The packing layout also depends on the seed, device, and fonts, so the page does not claim that any word belongs at a particular coordinate.
The area-corrected ggwordcloud option, area_corr, is a different choice. It shrinks or grows labels so each whole text box better follows the count, which trades the length bias for a letter-height bias because short words get taller type. Cleveland and McGill did not test word clouds; Felix and colleagues later found that bar length beat font size for judging values.
The short part of the text alternative is the cloud’s alt text: “Word cloud of the same 22 count-table words. The largest words by count are government with 585 and people with 561; the exact positions are not data. The full count table above is the long text alternative.” The long part is the sorted count table above, which lists every word and count used in the cloud.
Change the seed, not the data
The next cloud uses the identical keyed counts and a different seed. It is still the same input table.
Figure 3: The same 22 count-table words drawn again with seed 7702.
If the two pictures feel different, that feeling is the warning. The counts did not change.
Check preprocessing sensitivity
Stop-word lists are editorial choices. The table below recomputes the top words with three named choices: onix only, snowball only, and all three tidytext lexicons together.
Top words change when the stop-word lexicon changes
Stop-word choice
Rank
Word
Count
onix only
1
government
585
onix only
2
people
561
onix only
3
so
384
onix only
4
country
306
onix only
5
world
305
onix only
6
nation
299
onix only
7
citizens
242
onix only
8
own
242
onix only
9
peace
240
onix only
10
power
240
snowball only
1
will
940
snowball only
2
government
585
snowball only
3
people
561
snowball only
4
us
468
snowball only
5
can
456
snowball only
6
upon
369
snowball only
7
must
359
snowball only
8
great
342
snowball only
9
states
331
snowball only
10
may
326
all tidytext lexicons
1
government
585
all tidytext lexicons
2
people
561
all tidytext lexicons
3
country
306
all tidytext lexicons
4
world
305
all tidytext lexicons
5
nation
299
all tidytext lexicons
6
citizens
242
all tidytext lexicons
7
peace
240
all tidytext lexicons
8
power
240
all tidytext lexicons
9
public
224
all tidytext lexicons
10
time
214
With snowball only, common words such as will, us, and states remain. With onix, states is removed while united remains. A cloud without this preprocessing note would look more objective than it is.
Check the word-length trap
The next table compares real words from the count table. The rough space score is letters * sqrt(count). It is not a perception model; it only shows why a long word can occupy more horizontal room even when its count is lower. Alexander and coauthors tested word-length effects in word clouds; Felix, Franconeri, and Bertini tested magnitude judgments for several visual encodings, not word length.
length_pairs <- inaugural_word_counts |>filter(word_key %in%c("constitution", "time", "peace", "government", "people")) |>transmute( word_key, count, letters,rough_horizontal_space =round(letters *sqrt(count), 1) ) |>arrange(desc(rough_horizontal_space))kable( length_pairs,col.names =c("Word", "Count", "Letters", "Rough space score"),caption ="Long words can cover more space than shorter words with higher counts",row.names =FALSE)
Long words can cover more space than shorter words with higher counts
Word
Count
Letters
Rough space score
government
585
10
241.9
constitution
207
12
172.6
people
561
6
142.1
peace
240
5
77.5
time
214
4
58.5
constitution appears 207 times and time appears 214 times. The longer word can still take about 3 times the horizontal space under this simple geometry check. That is why Iris should not ask readers to compare close counts from font size.
What this cloud does not show
The cloud does not show word order, phrases, relationships, distinctiveness, change over time, or importance. It also does not show that united and states were part of a phrase before preprocessing split and filtered them.
Use a cloud as a doorway to the table, not as the table’s replacement.
What to remember
A word cloud starts from a count table; keep that table visible.
The onix stop-word lexicon removes states but keeps united in this corpus.
The bar chart and both clouds here use the same 22 keyed counts.
Word-cloud placement, adjacency, centre position, and colour carry no meaning.
Long words can look stronger than shorter words with similar counts.
Sorted counts are the long text alternative for the cloud.
Iris keeps the cloud, but the slide title points to the count table: “Common words after one stated cleanup.”