Projecting word vectors onto a map

Measure what the picture keeps and what it loses

information visualization
word embeddings
dimensionality reduction
Learn how PCA and t-SNE draw word embeddings in two dimensions while preserving only part of the original neighbourhoods.

Theo wants to show a small word-vector model on one slide. A scatterplot feels like a map, and maps invite stories.

This picture needs a warning label. Each word begins as 50 numbers. A two-dimensional drawing can keep some nearby neighbours and lose others.

Word embedding visualization draws word vectors as points by projecting many numeric dimensions into two. The plot is a question to check, not a finding about topics, clusters, or meaning.

TipWhat you will learn

This lesson shows how to:

  • verify the pinned inaugural word2vec model before loading it;
  • L2-normalize rows so Euclidean projection distances match cosine neighbours;
  • select a stated subset of frequent words;
  • compare PCA with t-SNE using 10-nearest-neighbour preservation;
  • check two t-SNE seeds instead of trusting one run; and
  • avoid reading clusters, gaps, sizes, and axis directions as evidence.

Load and verify the pinned model

The model comes from lesson 61. It is deliberately small: the metadata records 134,419 cleaned training tokens and a 50-dimensional skip-gram word2vec fit. In lesson 61, even the easy pair freedom / liberty landed below the median of all pairwise similarities, so this lesson measures whether the picture keeps the model’s neighbours. It does not claim the model learned reliable meaning.

library(dplyr)
library(tidyr)
library(tibble)
library(stringr)
library(readr)
library(tidytext)
library(quanteda)
library(word2vec)
library(Rtsne)
library(ggplot2)
library(knitr)
library(digest)

source("R/inaugural-corpus.R")

metadata <- read_csv(
  "data/word2vec/word2vec-metadata.csv",
  na = character(),
  col_types = cols(
    field = col_character(),
    value = col_character()
  )
)
metadata_values <- setNames(metadata$value, metadata$field)

model_path <- "data/word2vec/inaugural-word2vec.bin"
model_sha256 <- digest(file = model_path, algo = "sha256")
expected_model_sha256 <- metadata_values[["sha256_model"]]

stopifnot(
  identical(model_sha256, expected_model_sha256)
)

word2vec_model <- word2vec::read.word2vec(model_path)
embedding_matrix <- as.matrix(word2vec_model)

model_summary <- tibble(
  item = c(
    "training tokens",
    "vocabulary rows",
    "dimensions",
    "algorithm",
    "model SHA-256 matches metadata"
  ),
  value = c(
    metadata_values[["training_tokens"]],
    metadata_values[["vocabulary_rows"]],
    metadata_values[["dimensions"]],
    metadata_values[["algorithm"]],
    as.character(identical(model_sha256, expected_model_sha256))
  )
)

kable(
  model_summary,
  col.names = c("Model check", "Value"),
  caption = "Pinned word2vec model loaded for projection",
  row.names = FALSE
)
Pinned word2vec model loaded for projection
Model check Value
training tokens 134419
vocabulary rows 2709
dimensions 50
algorithm skip-gram
model SHA-256 matches metadata TRUE

The fingerprint check fails closed if the binary changes. Rendering does not train, download, or update a model.

Choose the plotted words

The full saved vocabulary has 2,709 rows, including the trainer’s </s> marker. This page plots the 300 most frequent training words that also have vectors. Changing the subset can change the projection.

paragraphs <- inaugural_paragraphs()

training_text <- tokens(
  str_to_lower(paragraphs$paragraph, locale = "en"),
  remove_punct = TRUE,
  remove_numbers = TRUE
) |>
  vapply(paste, character(1), collapse = " ")

training_frequencies <- tibble(text = training_text) |>
  unnest_tokens(word, text) |>
  count(word, sort = TRUE, name = "cleaned_paragraph_count") |>
  filter(word %in% rownames(embedding_matrix), word != "</s>")

subset_n <- 300L
selected_words <- training_frequencies |>
  slice_head(n = subset_n)

selected_embeddings <- embedding_matrix[selected_words$word, , drop = FALSE]
embedding_norms <- sqrt(rowSums(selected_embeddings^2))
normalized_embeddings <- selected_embeddings / embedding_norms
rownames(normalized_embeddings) <- selected_words$word

subset_summary <- tibble(
  item = c("plotted words", "minimum cleaned count", "maximum cleaned count"),
  value = c(
    nrow(selected_words),
    min(selected_words$cleaned_paragraph_count),
    max(selected_words$cleaned_paragraph_count)
  )
)

kable(
  selected_words |>
    slice_head(n = 12),
  col.names = c("Word", "Count in cleaned paragraphs"),
  caption = "The most frequent plotted words before projection",
  row.names = FALSE
)
The most frequent plotted words before projection
Word Count in cleaned paragraphs
the 10003
of 7057
and 5300
to 4523
in 2746
a 2244
our 2176
that 1783
we 1713
be 1490
is 1428
it 1395
kable(
  subset_summary,
  col.names = c("Subset check", "Value"),
  caption = "Projection subset for this lesson",
  row.names = FALSE
)
Projection subset for this lesson
Subset check Value
plotted words 300
minimum cleaned count 49
maximum cleaned count 10003

L2 normalization makes each row length equal to 1. On unit-length rows, Euclidean distance ranks neighbours the same way as cosine similarity, the measure used in lesson 61. The count column is an approximate training count rebuilt from the cleaned paragraphs with tidytext’s tokenizer, not a byte-for-byte count from word2vec’s internal splitter.

Project with PCA

PCA, short for principal component analysis, finds directions with the most spread in the normalized vectors. The table below reports how much variance the first two components hold. The rest is invisible in this plot.

pca_fit <- prcomp(normalized_embeddings, center = TRUE, scale. = FALSE)
pca_variance <- pca_fit$sdev^2 / sum(pca_fit$sdev^2)
pca_scores <- pca_fit$x[, 1:2, drop = FALSE]

if (pca_scores["government", "PC1"] < 0) {
  pca_scores[, "PC1"] <- -pca_scores[, "PC1"]
}

if (pca_scores["freedom", "PC2"] < 0) {
  pca_scores[, "PC2"] <- -pca_scores[, "PC2"]
}

pca_points <- as_tibble(pca_scores, rownames = "word") |>
  rename(x = PC1, y = PC2) |>
  left_join(selected_words, by = join_by(word))

label_words <- c(
  "government", "people", "freedom", "union",
  "peace", "constitution", "war", "america"
)

nearest_by_similarity <- function(matrix, k = 10L) {
  similarity <- tcrossprod(matrix)
  diag(similarity) <- NA_real_
  t(apply(
    similarity,
    1,
    \(values) names(sort(values, decreasing = TRUE))[seq_len(k)]
  ))
}

make_anchor_panel_data <- function(points, anchors, neighbour_matrix) {
  bind_rows(lapply(
    anchors,
    \(anchor) {
      points |>
        mutate(
          anchor_word = anchor,
          panel_role = case_when(
            word == anchor ~ "anchor word",
            word %in% neighbour_matrix[anchor, ] ~ "10 full-space neighbours",
            TRUE ~ "other plotted words"
          )
        )
    }
  )) |>
    mutate(
      anchor_word = factor(anchor_word, levels = anchors),
      panel_role = factor(
        panel_role,
        levels = c(
          "other plotted words",
          "10 full-space neighbours",
          "anchor word"
        )
      )
    )
}

full_space_neighbours <- nearest_by_similarity(normalized_embeddings, 10L)
pca_panel_points <- make_anchor_panel_data(
  pca_points,
  label_words,
  full_space_neighbours
)

pca_variance_table <- tibble(
  component = c("PC1", "PC2", "PC1 plus PC2"),
  variance_explained = c(
    pca_variance[1],
    pca_variance[2],
    sum(pca_variance[1:2])
  )
)

kable(
  pca_variance_table |>
    mutate(variance_explained = sprintf("%.1f%%", 100 * variance_explained)),
  col.names = c("PCA component", "Variance explained"),
  caption = "Variance visible in the two-dimensional PCA plot",
  row.names = FALSE
)
Variance visible in the two-dimensional PCA plot
PCA component Variance explained
PC1 13.3%
PC2 10.5%
PC1 plus PC2 23.9%
ggplot(pca_panel_points, aes(x = x, y = y)) +
  geom_point(
    data = pca_panel_points |>
      filter(panel_role == "other plotted words"),
    color = "#3B5F8A",
    alpha = 0.22,
    size = 0.8
  ) +
  geom_point(
    data = pca_panel_points |>
      filter(panel_role == "10 full-space neighbours"),
    color = "#8A5F3B",
    fill = "white",
    shape = 22,
    stroke = 0.7,
    size = 2.2
  ) +
  geom_point(
    data = pca_panel_points |>
      filter(panel_role == "anchor word"),
    color = "#1F2D3D",
    fill = "white",
    shape = 24,
    stroke = 0.9,
    size = 3.6
  ) +
  facet_wrap(vars(anchor_word), ncol = 4) +
  labs(
    x = "First principal component",
    y = "Second principal component"
  ) +
  theme_minimal()
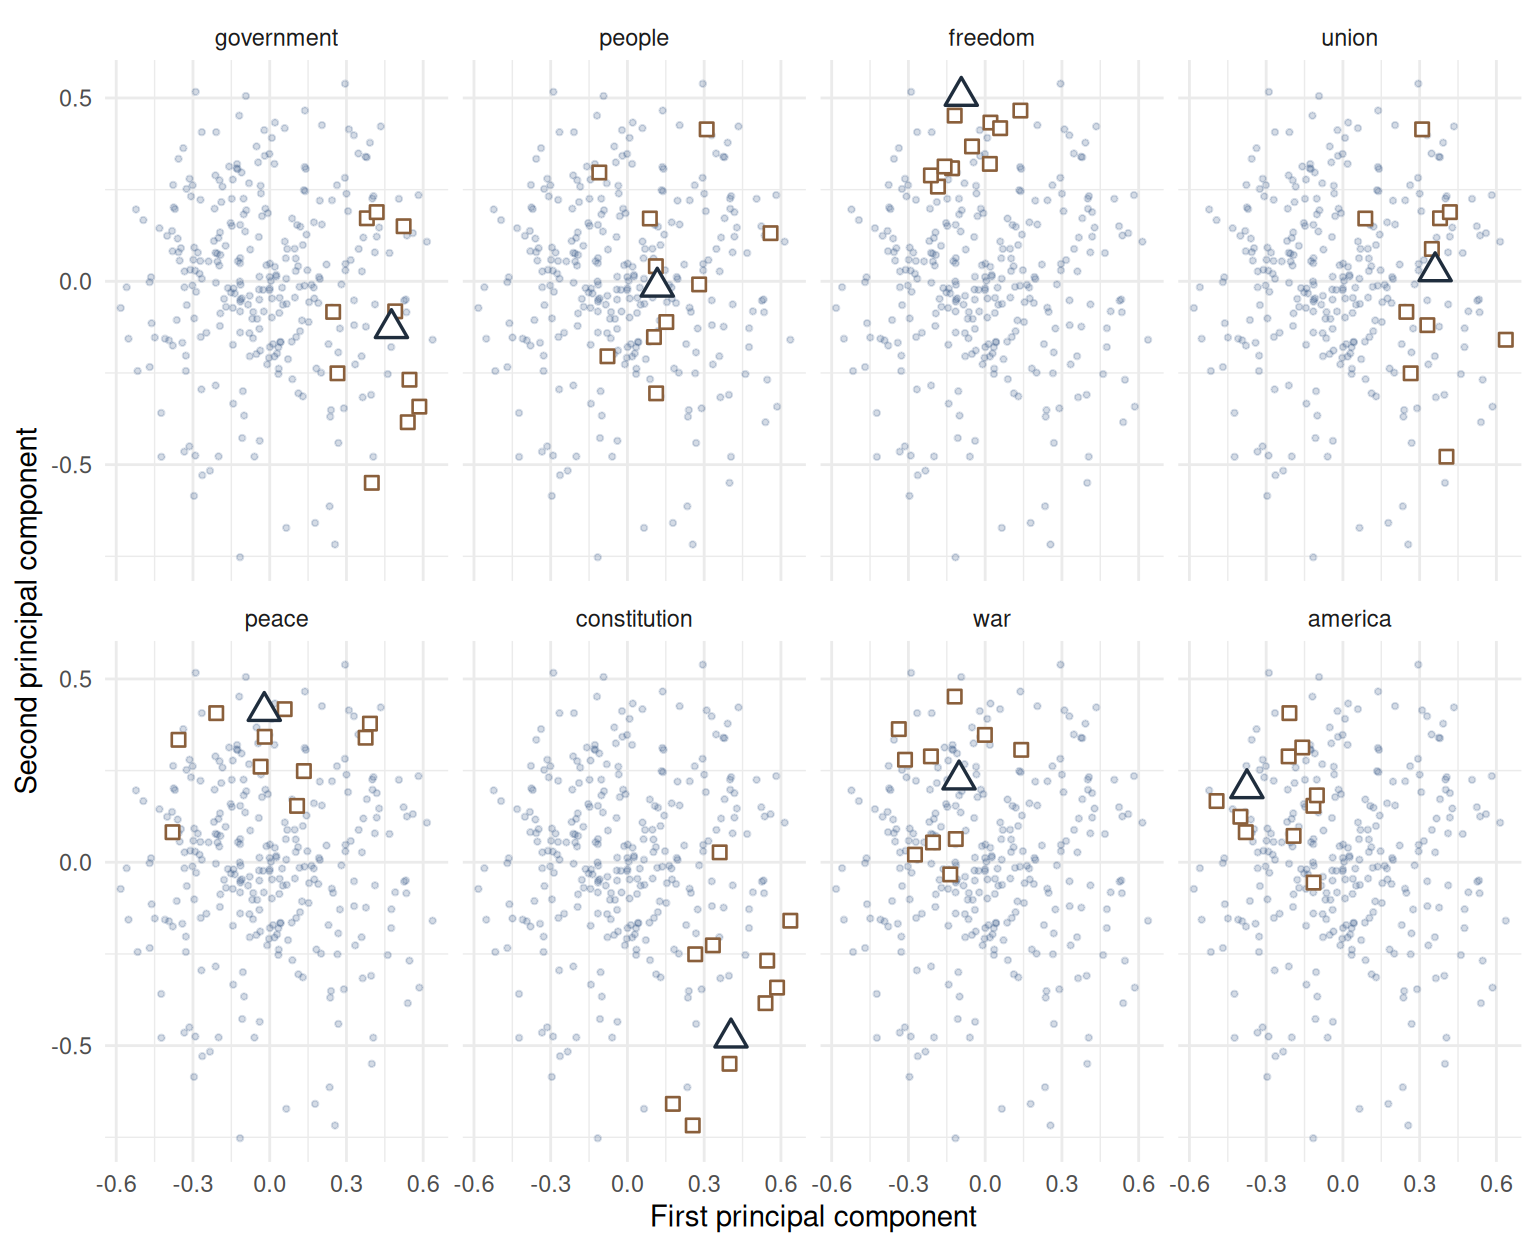
Eight-panel PCA small multiple. Each panel is named for one anchor word. Every panel shows the other 289 projected words as faint dots, the anchor word as a larger triangle, and its 10 full-space nearest neighbours as squares; the first two PCA components explain about 23.9 percent of variance.
Figure 1: PCA projection shown as one panel per anchor word. In each panel, faint dots are the other 289 plotted words, squares are that anchor’s 10 nearest neighbours in the full 50-dimensional vectors, and the large triangle is the anchor word.

PCA axes can flip sign across software builds, so the code fixes the signs with named anchor words before plotting. This lesson does not interpret left, right, up, or down. Each anchor word gets its own panel in both projection plots. The facet strip names the anchor, the large triangle marks the anchor, and squares mark all 10 of its nearest neighbours in the full vector space.

Project with t-SNE

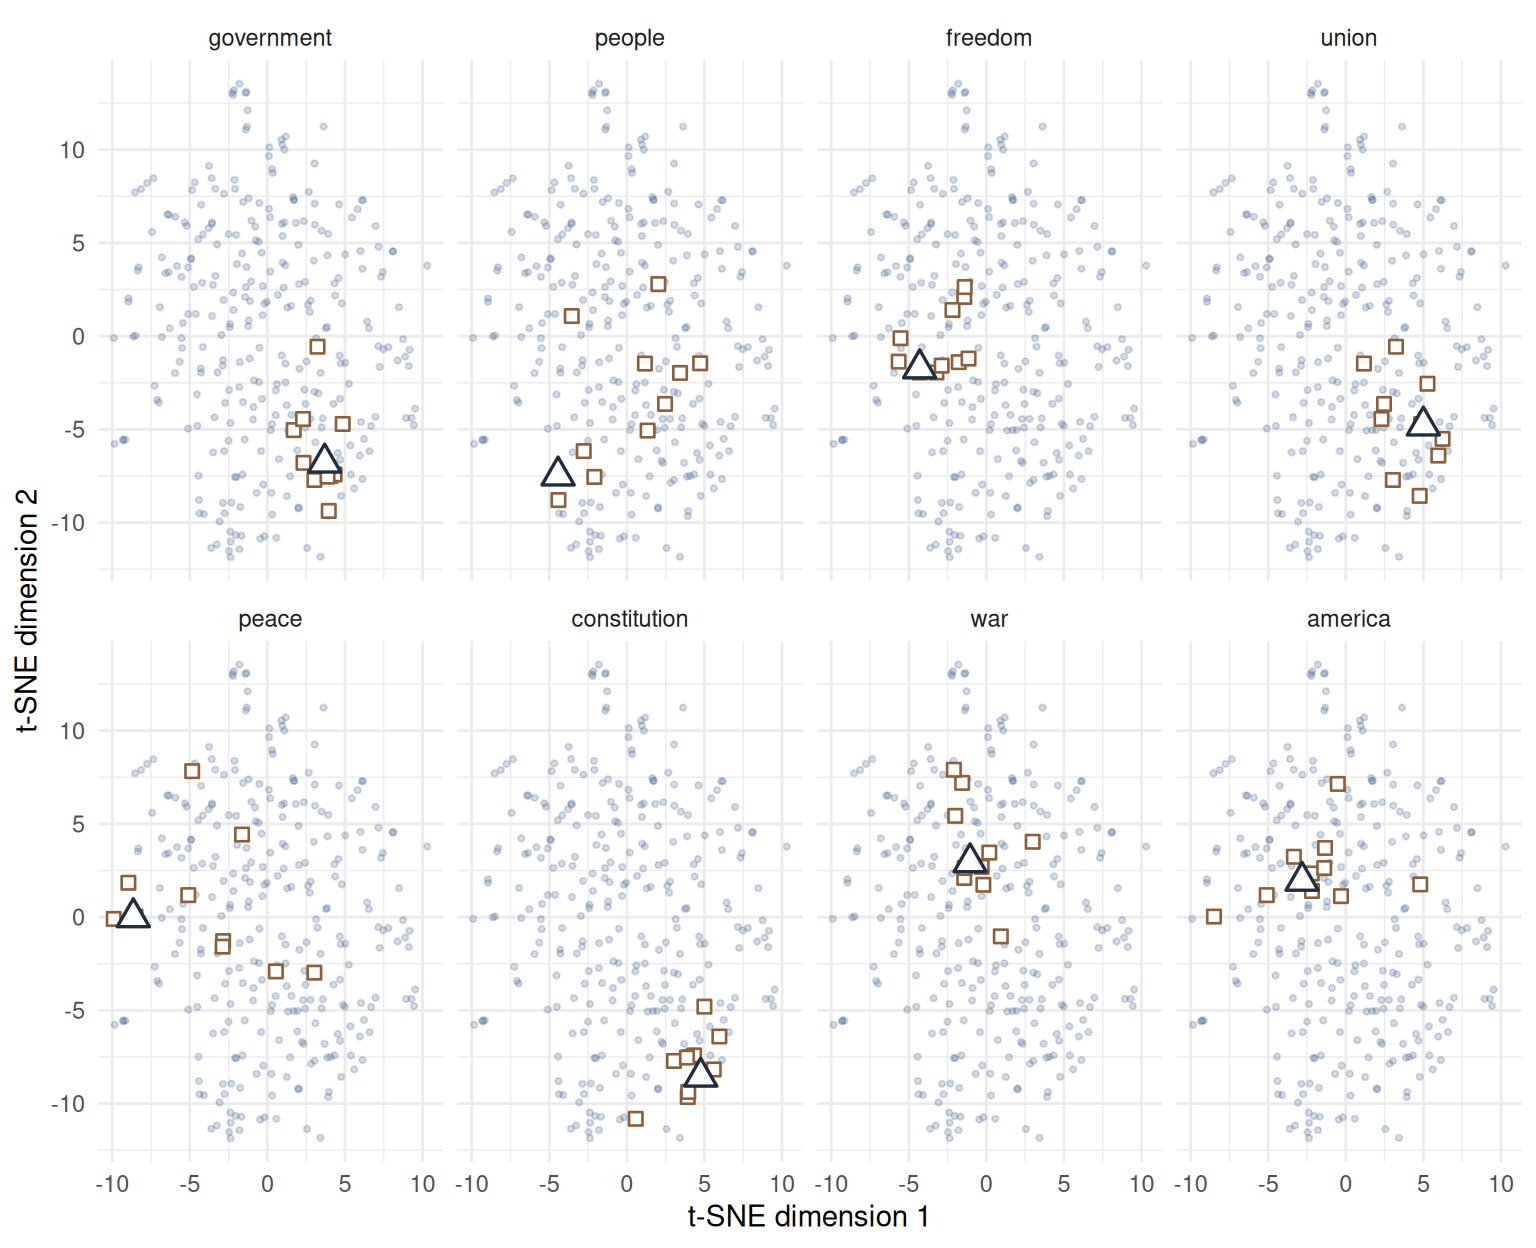
t-SNE is a stochastic method that tries to keep local neighbours together in the drawing. It can make groups and gaps that are not stable evidence. Here, perplexity 30 is a t-SNE setting for roughly how many neighbours each point considers; it is unrelated to the language-model perplexity in lessons 63 and 64. Theta 0.5 trades a little accuracy for speed, and 750 iterations is the number of optimization updates. The run also uses seed 7801, no initial PCA step, no extra normalization, and one thread.

tsne_perplexity <- 30
tsne_iterations <- 750L
tsne_theta <- 0.5
normalized_rows_unique <- !any(duplicated(as.data.frame(normalized_embeddings)))

stopifnot(
  normalized_rows_unique,
  3 * tsne_perplexity < nrow(normalized_embeddings) - 1
)

set.seed(7801)
tsne_seed_7801 <- Rtsne(
  normalized_embeddings,
  dims = 2,
  perplexity = tsne_perplexity,
  theta = tsne_theta,
  max_iter = tsne_iterations,
  pca = FALSE,
  normalize = FALSE,
  check_duplicates = FALSE,
  num_threads = 1,
  verbose = FALSE
)

tsne_points <- as_tibble(tsne_seed_7801$Y, .name_repair = "minimal") |>
  setNames(c("x", "y")) |>
  mutate(word = rownames(normalized_embeddings), .before = 1) |>
  left_join(selected_words, by = join_by(word))

tsne_labels <- tsne_points |>
  filter(word %in% label_words)
tsne_panel_points <- make_anchor_panel_data(
  tsne_points,
  label_words,
  full_space_neighbours
)

tsne_settings <- tibble(
  setting = c("seed", "perplexity", "iterations", "theta", "threads"),
  value = c(
    "7801",
    as.character(tsne_perplexity),
    as.character(tsne_iterations),
    as.character(tsne_theta),
    "1"
  )
)

kable(
  tsne_settings,
  col.names = c("t-SNE setting", "Value"),
  caption = "Settings for the plotted t-SNE run",
  row.names = FALSE
)
Settings for the plotted t-SNE run
t-SNE setting Value
seed 7801
perplexity 30
iterations 750
theta 0.5
threads 1
ggplot(tsne_panel_points, aes(x = x, y = y)) +
  geom_point(
    data = tsne_panel_points |>
      filter(panel_role == "other plotted words"),
    color = "#3B5F8A",
    alpha = 0.22,
    size = 0.8
  ) +
  geom_point(
    data = tsne_panel_points |>
      filter(panel_role == "10 full-space neighbours"),
    color = "#8A5F3B",
    fill = "white",
    shape = 22,
    stroke = 0.7,
    size = 2.2
  ) +
  geom_point(
    data = tsne_panel_points |>
      filter(panel_role == "anchor word"),
    color = "#1F2D3D",
    fill = "white",
    shape = 24,
    stroke = 0.9,
    size = 3.6
  ) +
  facet_wrap(vars(anchor_word), ncol = 4) +
  labs(
    x = "t-SNE dimension 1",
    y = "t-SNE dimension 2"
  ) +
  theme_minimal()
Eight-panel t-SNE small multiple using seed 7801. Each panel is named for one anchor word. Every panel shows the other 289 projected words as faint dots, the anchor word as a larger triangle, and its 10 full-space nearest neighbours as squares; the preservation table reports how often those neighbours stay near each other in two dimensions.
Figure 2: t-SNE projection shown as one panel per anchor word, using seed 7801. In each panel, faint dots are the other 289 plotted words, squares are that anchor’s 10 nearest neighbours in the full 50-dimensional vectors, and the large triangle is the anchor word.

The panels are landmarks so the two pictures can be matched by eye. They are not cluster names. Squares mark all 10 full-space neighbours; where they land shows whether the projection kept them near the anchor. The table below lists every anchor word.

Measure neighbour preservation

A 10-nearest-neighbour preservation score asks: for each word, what share of its 10 nearest neighbours in the full 50-dimensional normalized vectors also appear among its 10 nearest neighbours in the two-dimensional drawing? Chance is 10 divided by 299, or 3.3%.

nearest_by_distance <- function(points, k = 10L) {
  distances <- as.matrix(dist(points))
  diag(distances) <- Inf
  t(apply(
    distances,
    1,
    \(values) names(sort(values))[seq_len(k)]
  ))
}

neighbour_overlap <- function(first, second) {
  mean(vapply(
    seq_len(nrow(first)),
    \(row) sum(first[row, ] %in% second[row, ]) / ncol(first),
    numeric(1)
  ))
}

pca_matrix <- pca_points |>
  select(x, y) |>
  as.matrix()
rownames(pca_matrix) <- pca_points$word

stopifnot(
  identical(rownames(full_space_neighbours), rownames(pca_matrix))
)

pca_neighbours <- nearest_by_distance(pca_matrix, 10L)
rownames(pca_neighbours) <- pca_points$word

tsne_matrix_7801 <- tsne_points |>
  select(x, y) |>
  as.matrix()
rownames(tsne_matrix_7801) <- tsne_points$word

stopifnot(
  identical(rownames(full_space_neighbours), rownames(tsne_matrix_7801))
)

tsne_neighbours_7801 <- nearest_by_distance(tsne_matrix_7801, 10L)
rownames(tsne_neighbours_7801) <- tsne_points$word

set.seed(7802)
tsne_seed_7802 <- Rtsne(
  normalized_embeddings,
  dims = 2,
  perplexity = tsne_perplexity,
  theta = tsne_theta,
  max_iter = tsne_iterations,
  pca = FALSE,
  normalize = FALSE,
  check_duplicates = FALSE,
  num_threads = 1,
  verbose = FALSE
)

tsne_points_7802 <- as_tibble(tsne_seed_7802$Y, .name_repair = "minimal") |>
  setNames(c("x", "y")) |>
  mutate(word = rownames(normalized_embeddings), .before = 1)

tsne_matrix_7802 <- tsne_points_7802 |>
  select(x, y) |>
  as.matrix()
rownames(tsne_matrix_7802) <- tsne_points_7802$word

stopifnot(
  identical(rownames(full_space_neighbours), rownames(tsne_matrix_7802)),
  identical(rownames(tsne_neighbours_7801), rownames(tsne_matrix_7802))
)

tsne_neighbours_7802 <- nearest_by_distance(tsne_matrix_7802, 10L)
rownames(tsne_neighbours_7802) <- tsne_points_7802$word

preservation_table <- tibble(
  comparison = c(
    "PCA versus full-space neighbours",
    "t-SNE seed 7801 versus full-space neighbours",
    "t-SNE seed 7802 versus full-space neighbours",
    "t-SNE seed 7801 versus t-SNE seed 7802",
    "chance level for a random 10-word set"
  ),
  preservation = c(
    neighbour_overlap(full_space_neighbours, pca_neighbours),
    neighbour_overlap(full_space_neighbours, tsne_neighbours_7801),
    neighbour_overlap(full_space_neighbours, tsne_neighbours_7802),
    neighbour_overlap(tsne_neighbours_7801, tsne_neighbours_7802),
    10 / (nrow(normalized_embeddings) - 1)
  )
)

display_preservation <- preservation_table |>
  mutate(preservation = sprintf("%.1f%%", 100 * preservation))

kable(
  display_preservation,
  col.names = c("Comparison", "Average 10-neighbour overlap"),
  caption = "Neighbour preservation for two-dimensional projections",
  row.names = FALSE
)
Neighbour preservation for two-dimensional projections
Comparison Average 10-neighbour overlap
PCA versus full-space neighbours 17.5%
t-SNE seed 7801 versus full-space neighbours 43.1%
t-SNE seed 7802 versus full-space neighbours 42.6%
t-SNE seed 7801 versus t-SNE seed 7802 50.8%
chance level for a random 10-word set 3.3%

The measured result is modest but useful. PCA keeps about 17.5% of each word’s 10 neighbours. The plotted t-SNE run keeps about 43.1%, and the second t-SNE seed keeps about 42.6%. The two t-SNE runs agree with each other on about 50.8% of neighbours. That is well above chance, but it is not perfect stability.

Inspect labelled words as rows

The table below is the text alternative for the labelled points. It reports neighbours from the full vector space and from the two plotted projections, without asking the reader to infer them from point positions.

neighbour_table <- tibble(word = label_words) |>
  rowwise() |>
  mutate(
    full_space_neighbours = paste(full_space_neighbours[word, 1:5], collapse = ", "),
    pca_neighbours = paste(pca_neighbours[word, 1:5], collapse = ", "),
    tsne_neighbours = paste(tsne_neighbours_7801[word, 1:5], collapse = ", ")
  ) |>
  ungroup()

kable(
  neighbour_table,
  col.names = c(
    "Labelled word",
    "Nearest in 50 dimensions",
    "Nearest in PCA plot",
    "Nearest in t-SNE plot"
  ),
  caption = "Neighbour lists for the labelled words in the two projection figures",
  row.names = FALSE
)
Neighbour lists for the labelled words in the two projection figures
Labelled word Nearest in 50 dimensions Nearest in PCA plot Nearest in t-SNE plot
government principle, authority, system, action, laws revenue, within, law, general, justice constitutional, laws, authority, right, power
people character, citizens, interests, honor, course while, themselves, another, in, both citizens, country, americans, fellow, honor
freedom human, progress, yet, democracy, liberty progress, peace, human, life, world human, liberty, their, faith, our
union system, federal, institutions, success, constitution means, whole, or, of, national system, general, within, foreign, policy
peace world, prosperity, all, order, strong toward, human, life, even, strength world, nations, men, all, among
constitution authority, executive, president, constitutional, congress executive, duty, constitutional, united, proper states, executive, authority, laws, powers
war progress, still, force, old, yet good, end, seek, greater, men yet, made, end, progress, through
america democracy, history, world, yet, hope we, done, us, work, nothing history, democracy, experience, way, spirit

If a nearby label looks interesting, the next step is to inspect the underlying texts or the full-space neighbour table. The picture alone is not evidence that the words form a topic.

What this does not show

The t-SNE plot does not give meaningful cluster sizes, gap sizes, group positions, or axis directions. PCA directions are mathematical summaries, but their signs can flip, and this plot still leaves most variance out.

The preservation scores are about the projection’s fidelity to this small model, not about fidelity to meaning. Small-corpus embeddings can change their neighbour lists when trained again, which is why this model is pinned. The same t-SNE seed can also draw a different layout on another computer because low-level numerical details can differ.

What to remember

  • Each plotted point began as a 50-number word vector.
  • Rows were L2-normalized before PCA and t-SNE so neighbours match cosine geometry.
  • PCA’s first two components explain about 23.9% of variance here.
  • t-SNE preserves more local neighbours than PCA in this run, but two seeds still disagree on many neighbours.
  • Do not interpret clusters, gaps, sizes, positions, or axis directions as findings.

Keep the scatterplot beside the preservation table. The table says what the picture kept.
Sources